How to Triage Customer Complaints at Scale
October 16, 2026
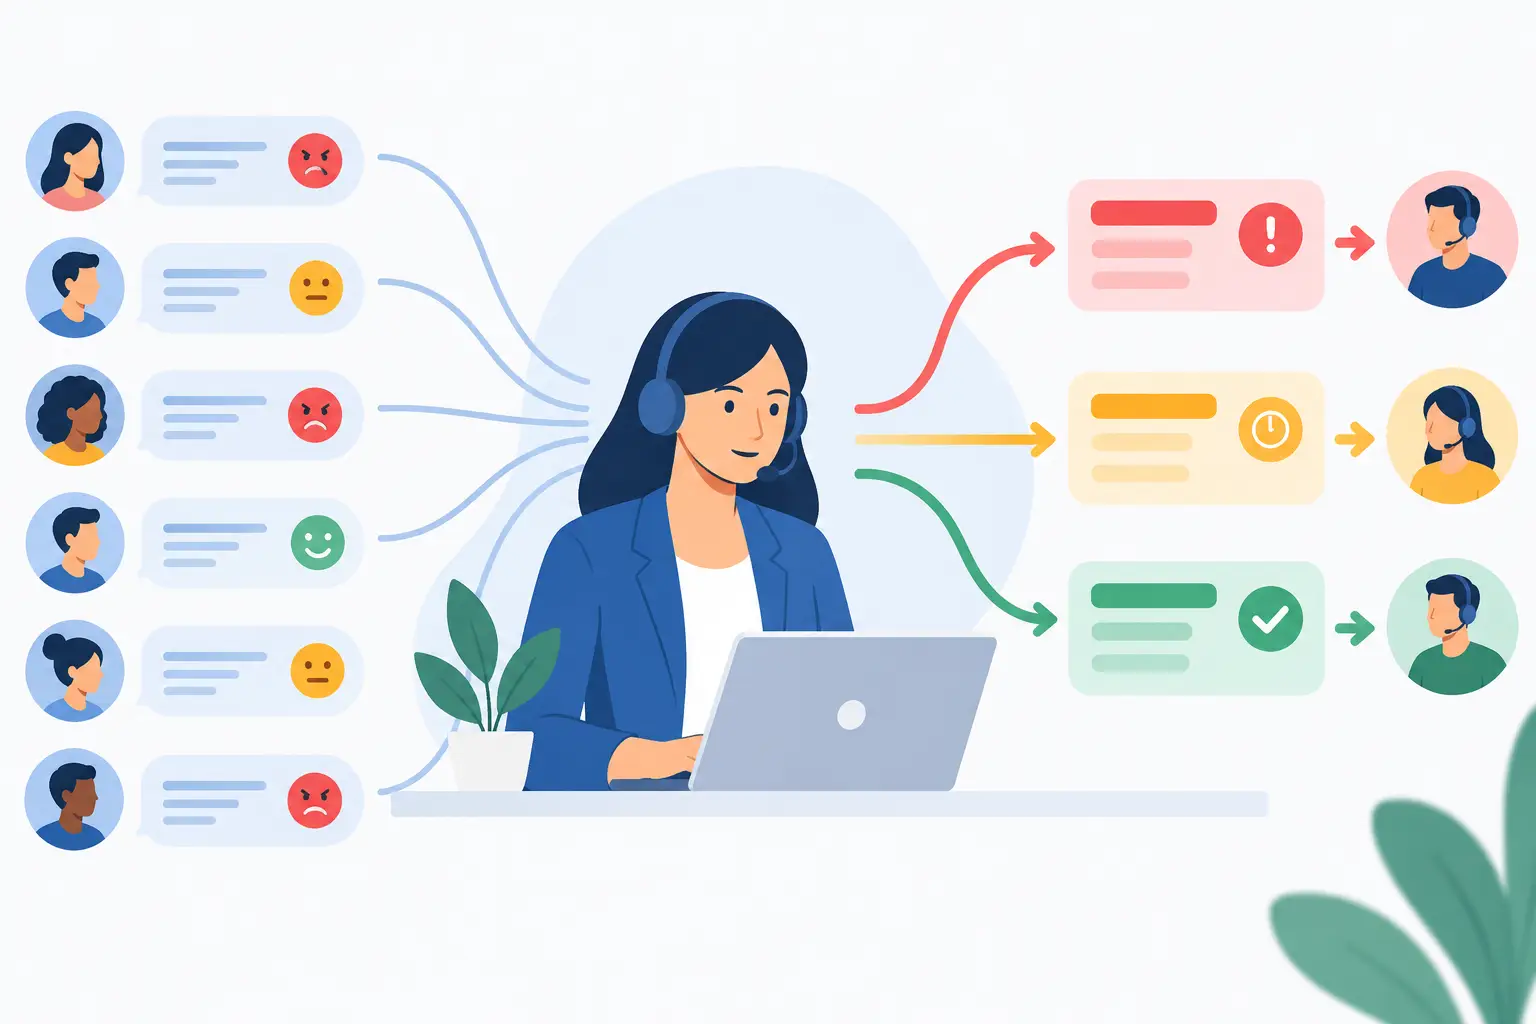
A complaint sitting in a shared inbox is not yet a customer-experience signal. It is an unassigned piece of evidence with an unknown level of risk. Knowing how to triage customer complaints turns that evidence into a controlled operational workflow: resolve the immediate issue, identify patterns, and make sure the right team owns the next action.
The challenge is rarely a lack of feedback. Most organizations already receive complaints through support tickets, emails, surveys, account reviews, work-order notes, social channels, and escalation calls. The difficulty is that each source has its own format, owner, and urgency rules. Triage creates one decision system across all of them.
What customer complaint triage is designed to do
Complaint triage is the process of assessing, prioritizing, routing, and tracking a complaint before it disappears into a general service queue. It separates issues that require an immediate response from those that need investigation, trend analysis, or a longer-term process change.
A good triage process does not treat every complaint as equally urgent. A delayed shipment and a data-security concern should not follow the same path. Nor should a single request for a product feature receive the same response as ten complaints about an invoice error introduced after a billing-system change.
The goal is not to reduce every customer concern to a score. It is to make decisions consistent, visible, and timely. Teams should be able to answer four questions for every material complaint: What happened? How serious is it? Who owns the response? What will prevent it from happening again?
How to triage customer complaints with a repeatable workflow
Centralize complaints without stripping away context
Begin by bringing complaint data into a common intake process. That does not mean forcing customers to use one channel. It means collecting the relevant details from every channel in a format that can be reviewed consistently.
At minimum, capture the customer or account, the original complaint text, source, date received, product or service involved, location or business unit when applicable, and any existing case or order number. Preserve the original language. A short category such as “service issue” is useful for reporting, but it should never replace the customer’s actual description.
Context also includes history. A complaint from a long-standing strategic account may have different retention implications than the same issue from a first-time buyer. Repeated contacts from the same customer can indicate an unresolved case, while similar complaints across many customers may reveal a systemic failure.
Centralization matters because fragmented intake produces fragmented judgment. When support sees the ticket, operations sees the work order, and leadership only sees a monthly satisfaction score, no one has the complete picture.
Assess severity using clear, shared criteria
Triage requires more than a sentiment label. An angry message is not always the highest-risk complaint, and a politely worded note can expose a serious safety, compliance, financial, or accessibility issue.
Use a small set of decision factors that frontline teams and managers can apply without interpretation drift:
- Customer impact: How severely has the customer been affected? Consider lost service, financial loss, safety, privacy, or inability to use a core product.
- Scope: Is this isolated, or could it affect multiple customers, locations, orders, or employee teams?
- Urgency: Does the issue require action now to prevent further harm, regulatory exposure, churn, or public escalation?
- Strategic significance: Does the complaint involve a key account, contractual commitment, high-value segment, or a known organizational priority?
- Recurrence: Has this issue appeared before, particularly in the same product, process, or operational period?
These factors can be converted into a score, but scoring is not mandatory. For lower-volume teams, a simple priority level may be more practical. The critical requirement is a documented definition for each level. If “high priority” means something different to every manager, the process will be inconsistent when volume increases.
For example, a complaint that alleges a privacy breach should be escalated immediately, even if only one customer is affected. A cluster of moderate complaints about missed appointments may merit a high operational priority because the pattern signals a capacity or scheduling problem. Triage should account for both the individual case and the emerging pattern.
Route the complaint to an accountable owner
Once a complaint is prioritized, assign two forms of ownership. The case owner is responsible for acknowledging the customer, providing updates, and documenting the resolution. The corrective-action owner is responsible for investigating the underlying process and delivering any needed change.
Those roles may be held by the same person for simple issues. They should be separate when the complaint involves a cross-functional failure. Customer support can resolve a refund request, for example, but finance may need to correct the invoice rule that caused the error.
Routing rules should specify where each category goes and when escalation is required. A service-recovery issue may go to a customer-success leader. A product defect may route to product and quality teams. A complaint involving legal, security, safety, or discrimination concerns needs a defined escalation path with restricted access and documented handling requirements.
Avoid assigning complaints to broad groups without a named owner. “Operations” is not ownership. A person, due date, and expected next step are ownership.
Separate case resolution from root-cause analysis
Closing a customer case does not necessarily mean the problem is solved. A customer may accept a replacement, credit, explanation, or apology while the operational condition that caused the complaint remains unchanged.
This is where teams often lose the value of complaint data. They track service-level performance, such as first response and closure time, but do not track whether recurring causes were addressed. Fast closure can even conceal a persistent defect if agents are repeatedly applying the same workaround.
Create a second workflow for complaints that meet a threshold for investigation. That threshold may be based on severity, recurrence, cost, account risk, or evidence of a process-control gap. Group related complaints by theme, product, journey stage, location, supplier, or operational event. Then use the grouped evidence to test the likely cause.
Be careful not to confuse a frequent phrase with a root cause. “Late delivery” describes an outcome. The cause may be inaccurate inventory availability, an unrealistic delivery promise, warehouse capacity constraints, a carrier handoff failure, or an address-validation error. Root-cause analysis should move from what customers experienced to the conditions that created the experience.
Build service levels around risk, not convenience
A triage system needs response expectations, but one universal deadline is rarely enough. High-risk complaints may require an immediate internal escalation and same-day customer acknowledgment. Standard service complaints can follow a longer window, provided the customer receives a clear expectation.
The right service level depends on the industry, contract terms, customer base, and regulatory obligations. Healthcare, financial services, utilities, and public-sector teams may require stricter handling than a low-risk business service. The principle remains consistent: response commitments should match the potential consequence of delay.
Track more than response speed. Useful operational measures include the percentage of complaints categorized within the target window, escalation compliance, reopened-case rate, recurrence by root-cause category, corrective-action completion, and the time from pattern detection to verified improvement.
These measures show whether the organization is merely processing complaints or actually reducing the conditions that create them.
Make complaint categories useful for decisions
Categories should support routing and analysis, not create administrative work. A short, stable category structure is usually more useful than a long taxonomy with overlapping labels. Start with the major experience or operational domains that leadership can act on, such as billing, product quality, delivery, communication, service access, account management, and policy.
Add subcategories only when they change the likely owner or action. For instance, “billing” may need subcategories for duplicate charge, incorrect price, unclear invoice, and payment failure because each can point to a different process. By contrast, adding several nearly identical labels for “agent was unhelpful” may create reporting noise without improving resolution.
Use complaint text to validate categories regularly. New themes emerge after a product launch, policy change, acquisition, or service disruption. A taxonomy that never changes eventually hides the exact signals leaders need to see.
Avoid the common failure modes
The first failure mode is treating triage as an inbox-management exercise. A clean queue is useful, but it is not the same as controlled risk or organizational learning.
The second is relying entirely on manual review. Human judgment is essential for sensitive cases, but manual sorting becomes unreliable when messages are spread across systems and volume rises. Teams spend their time finding complaints rather than understanding them.
The third is automating classification without governance. Automated tagging can speed intake, but it needs review rules, confidence thresholds, and a way to correct categories. Otherwise, inaccurate labels become inaccurate dashboards and poor decisions.
The fourth is reporting complaint counts without denominators. Ten complaints may be a serious issue for a small account base and insignificant for a high-volume transaction period. Compare complaint patterns with sales, service interactions, deliveries, active customers, or other relevant exposure measures.
Connect feedback intelligence to accountable action
The strongest triage systems connect every stage of the workflow: ingestion, classification, prioritization, case handling, root-cause review, and corrective action. A Complaint Dashboard can make risk and trends visible, while an Action Backlog ensures that recurring issues are not left as observations in a monthly report.
StatQuestions supports this model by organizing unstructured complaint text alongside surveys, emails, work-order notes, and other feedback sources. The objective is not simply to create a better dashboard. It is to give teams shared evidence, guided analysis, and a trackable path from complaint to decision.
The most useful complaint program is not the one with the fewest open cases. It is the one where customers see a timely response, leaders can see the patterns behind the volume, and teams can prove that the next complaint is less likely to happen for the same reason.