Text Analytics That Turns Feedback Into Action
October 6, 2026
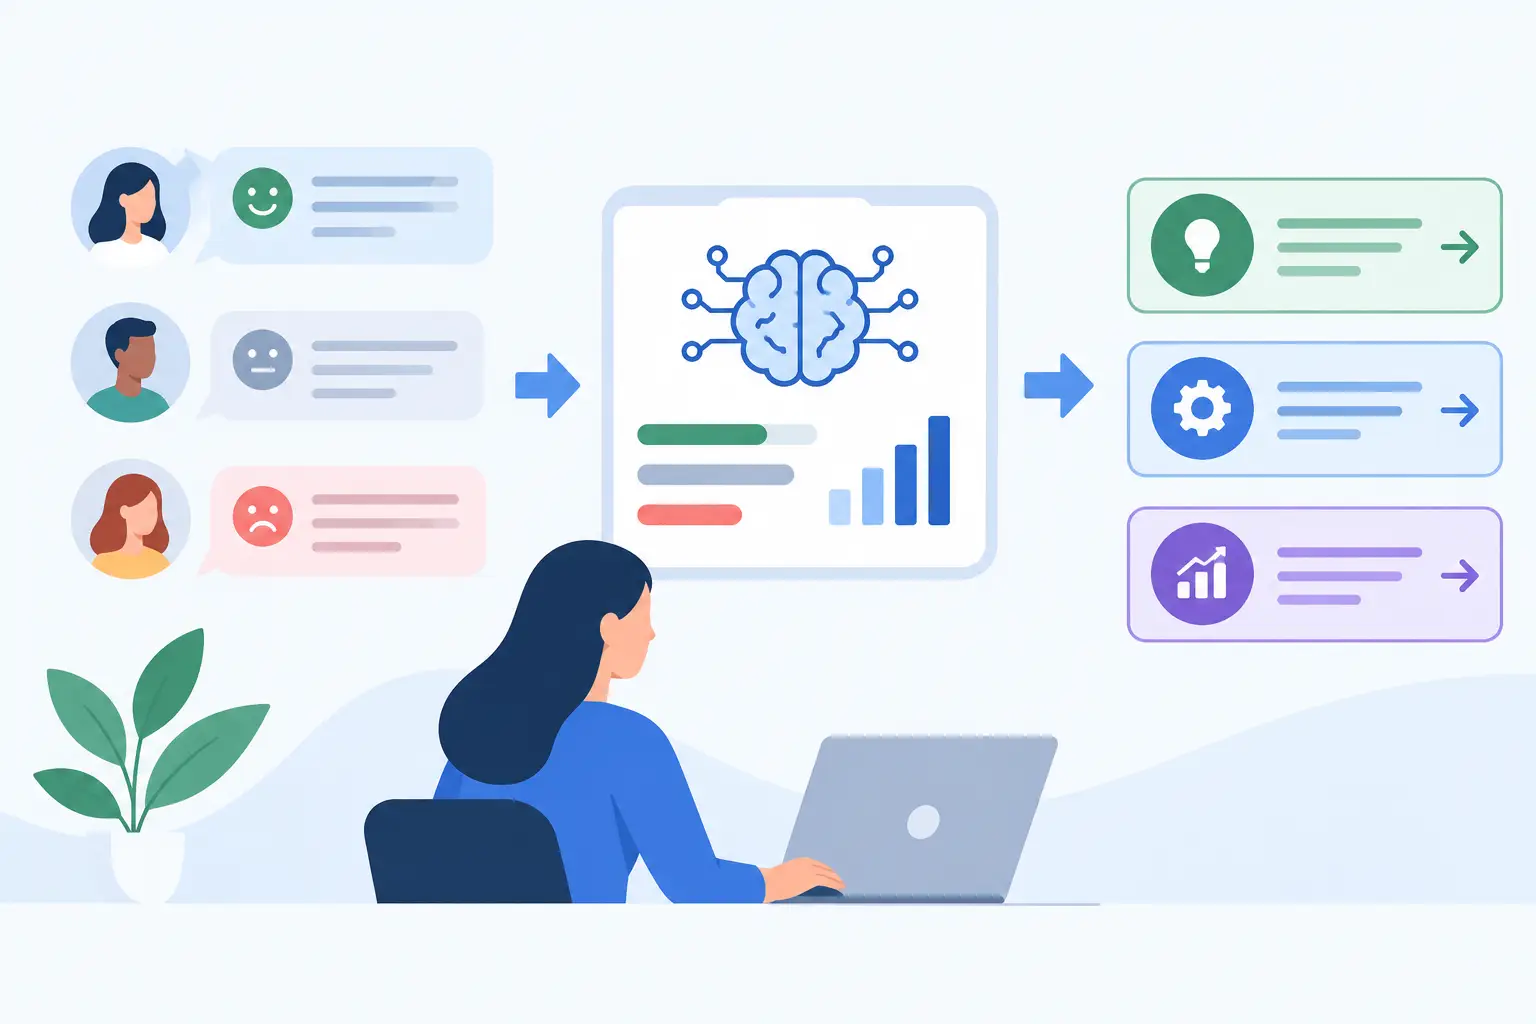
A service leader sees 2,000 support emails in a month, 600 open-ended survey comments, and a growing complaint queue. The dashboard may show that satisfaction declined, but it cannot explain the operational reason. Text analytics closes that gap by turning the language customers, employees, and stakeholders use every day into organized evidence that teams can investigate and act on.
For organizations with feedback spread across surveys, inboxes, case records, work-order notes, and CRM systems, the value is not simply faster reporting. It is the ability to connect recurring issues to the responsible process, owner, location, product, or service channel - then track whether corrective action changed the outcome.
What Text Analytics Does in an Operational Setting
Text analytics is the process of examining unstructured written feedback to identify patterns, classify themes, measure sentiment or intent, and surface meaningful exceptions. It gives structure to information that was written for human communication rather than reporting.
A customer may write, "The technician was courteous, but I had to call three times to get an appointment." That single comment contains more than a positive or negative score. It includes a service-quality signal, an appointment-access issue, and a possible repeat-contact indicator. At scale, text analytics helps an organization recognize whether this is an isolated experience or a recurring failure point.
The strongest programs do not treat comments as a side note to numeric data. They use text to explain the numbers. A drop in customer satisfaction may be concentrated around delayed callbacks. Lower employee engagement may reflect schedule instability, unclear policy changes, or manager communication. Complaint volume may rise because of a specific billing rule, product defect, or handoff between teams.
This work generally combines several capabilities: extracting key terms and phrases, assigning records to defined categories, detecting sentiment or urgency, grouping similar feedback, and comparing themes across segments and time periods. The right mix depends on the business question. A leadership team may need trend visibility, while an operations team may need a daily queue of records requiring review.
Text Analytics Is Not Just Sentiment Analysis
Sentiment analysis can be useful, but it is often too broad to manage an operation. Knowing that 38% of comments are negative does not tell a service leader what to fix first.
Consider the difference between these statements: "Customers are unhappy" and "Negative comments about appointment availability increased 42% after the scheduling-policy change, particularly among first-time customers in the Northeast." The second statement creates a path to investigation. It can be checked against staffing levels, appointment capacity, call abandonment, policy dates, and customer cohorts.
Sentiment also has limits. A complaint written in calm, factual language may carry a serious compliance or safety concern. A comment with strongly negative wording may be about a minor inconvenience. Teams need topic, context, severity, and operational metadata alongside sentiment.
That is why classification matters. A useful classification framework reflects the organization’s actual decisions. Categories such as billing, communication, scheduling, product quality, delivery, staff conduct, and policy can establish a common language across data sources. More detailed subcategories can then distinguish, for example, a confusing invoice from an incorrect charge or a delayed refund.
The goal is not to create the longest possible taxonomy. It is to create categories that are reliable enough to compare and specific enough to guide action.
Start With the Decisions Your Team Needs to Make
Many text analytics initiatives stall because teams begin with available data rather than a clear operating question. The result is an attractive word cloud, a lengthy list of topics, and no defined next step.
Start by identifying the decisions that feedback should support. A customer-experience team may need to determine which friction points most affect retention. A contact-center leader may need to find the drivers of repeat contact. An employee-experience group may need to identify what is behind declining confidence in leadership. A quality team may need to distinguish routine dissatisfaction from issues that require escalation.
Those decisions should shape the data model. If the question is whether service delays are damaging loyalty, the analysis needs text, dates, customer segment, service location, case type, outcome measures, and possibly operational timestamps. Reading comments without relevant context can produce plausible but incomplete conclusions.
It also helps to separate two workflows. One workflow is strategic: monitor trends, compare segments, identify emerging root causes, and prioritize improvement opportunities. The other is operational: identify individual complaints, risks, or recovery opportunities and route them to the appropriate owner. Both use text, but they require different timing, thresholds, and governance.
Build a Reliable Feedback Classification System
A classification system should make disparate feedback comparable without flattening its meaning. Survey comments, emails, complaint narratives, and technician notes may use different language to describe the same underlying issue. A customer may mention "no one called me back," while an internal note says "callback SLA missed." A well-designed framework can connect both records to communication or follow-up performance.
Begin with a manageable set of top-level themes tied to key processes. Define each category in plain language, including what belongs and what does not. Add examples from real organizational feedback. Then test the framework against a sample that includes different channels, products, locations, and customer types.
This validation stage is where operational expertise matters. Automated models can identify similarity and suggest labels, but someone who understands the service process must determine whether the category is meaningful and whether a record has been assigned correctly. Automation can accelerate review; it should not remove accountability for definitions that drive reporting and action.
Classification also needs maintenance. New products, policy changes, seasonal conditions, and public events change the language people use. A category that worked six months ago may now be too broad, too narrow, or missing a material issue. Review category performance on a regular schedule, especially when teams begin making decisions from the results.
Connect Themes to Root Causes and Actions
A recurring theme is not automatically a root cause. "Long wait times" may result from staffing gaps, demand spikes, scheduling rules, system outages, poor routing, or a process that creates unnecessary contacts. Text analytics identifies where to look. Root-cause analysis identifies why the issue persists.
This distinction protects teams from reacting to the loudest comments rather than the most consequential problem. A theme should be assessed using volume, trend direction, severity, affected population, business impact, and confidence in the evidence. A small number of comments about a safety issue may deserve immediate escalation. A high-volume complaint about a minor inconvenience may call for process improvement but not emergency response.
Once a priority is confirmed, the work should move into an action workflow. Assign an owner, document the proposed corrective action, set a due date, and define the measure that will indicate progress. If appointment communication is the issue, the measure might include missed-appointment contacts, repeat calls, appointment-related complaint volume, and satisfaction among affected customers.
An Action Backlog prevents insight from becoming a presentation artifact. It gives leaders visibility into what has been accepted, what is under investigation, what has been completed, and whether the expected change occurred.
Measure Accuracy, Adoption, and Business Value
A text analytics program should be evaluated on more than model performance. Classification accuracy matters, particularly for compliance, risk, and high-stakes routing. But a technically accurate system that no one uses to make decisions has limited value.
Monitor whether users trust the categories, whether records can be traced back to original text, and whether teams can explain why a trend was flagged. Sampling and human review are essential, especially when language is ambiguous, sarcastic, industry-specific, or emotionally charged.
Business value appears when feedback becomes part of the operating rhythm. Teams should be able to review emerging themes, compare them against numeric outcomes and operational data, open investigations, and track action status in one connected process. Platforms such as StatQuestions are designed around that lifecycle: ingesting feedback from existing sources, organizing it into usable classifications and dashboards, and carrying validated insights into accountable work.
The most useful text analytics program is not the one with the most categories or the most sophisticated model. It is the one that helps a team notice a meaningful problem early enough, understand it clearly enough, and assign the next right action before the same feedback becomes next quarter’s trend.